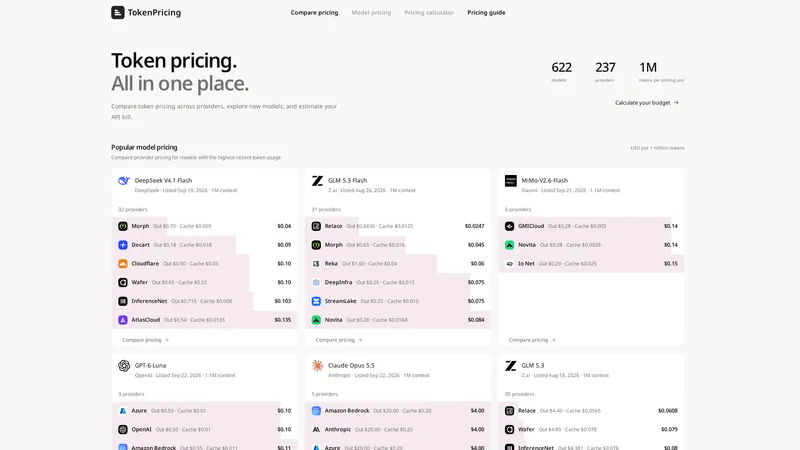
TokenPricing is a free, independent LLM API pricing comparison site. It tracks 622 models across 237 providers and lists input, output and cached token pricing in USD per 1 million tokens, so rates from OpenAI, Anthropic, Google, DeepSeek, Z.ai, Xiaomi and many hosting providers can be compared side by side. Every offer links to the page where its pricing was published, and a missing rate stays unknown instead of being shown as zero.
Each model page shows the official rate next to additional provider offers, with context window, capability tags, cache write, batch and web search charges, plus speed and uptime when a source reports them. A chart plots input against output price so the cheapest providers are easy to spot, and the homepage table can be filtered by 30 days, 90 days or all time.
The pricing calculator turns input tokens, output tokens, monthly requests and cache hit rate into an estimated monthly bill and cost per request, using published model pricing or your own custom rates. A pricing guide explains tokens, per-million conversion and prompt-cache pricing. The catalog is checked daily, and no signup is needed.
Key features:
- Input, output and cache-read pricing per 1M tokens for 622 models from 237 providers
- Source link on every offer; missing rates shown as unknown, not zero
- Model pages with official vs provider pricing, context, capabilities, speed and uptime
- Input vs output price chart to spot the cheapest providers
- Extra charges shown where published: cache write (5m/1h), batch, web search
- Token pricing calculator for monthly and per-request cost, with cache hit rate and custom rates
- Workload presets: Chat app, AI agent, High volume
- Searchable model table with 30d / 90d / all-time filters
- Pricing guide and FAQ on tokens, conversion and cached pricing
- Catalog checked daily. Free, no signup.
Use cases:
- Find the cheapest provider for a specific model (e.g. Claude Opus 5.5, DeepSeek V4.1 Flash, GLM 5.3 Flash)
- Estimate a monthly LLM API budget before launching an AI app or agent
- Measure how prompt caching changes total cost
- Compare official pricing with third-party or cloud reseller offers (Bedrock, Azure, Vertex, DeepInfra, Novita…)
- Check whether output pricing outweighs input pricing for long-answer workloads
- Convert per-token pricing to per-million pricing


