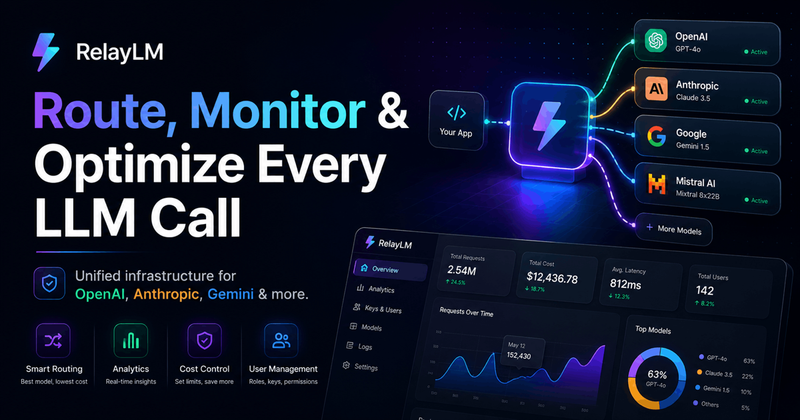
RelayLM is an AI gateway and cost-control layer that routes OpenAI and Anthropic API calls through a single endpoint so teams can monitor per-user token spend and enforce budget limits before production costs spike.
What is RelayLM?
RelayLM is an AI gateway and spend-control layer for teams building on the OpenAI and Anthropic APIs. Your application sends model requests to RelayLM instead of to the provider directly; RelayLM forwards them using the provider keys you configure, logs each request with its token count and calculated cost, attributes that spend to a specific user or service, and displays it in a dashboard where budgets and rate limits can be set. It is a hosted web product accessed with an API key generated in the dashboard, and it is currently in private early access, with a public launch stated for 18 August 2026.
What makes RelayLM stand out?
- Spend guardrails — project budgets and per-user limits are enforced by a rate-limiting proxy, so a cap applies while requests are being made rather than after the invoice arrives.
- Per-user attribution — every call is tied to the user, service, or agent that made it, so the dashboard can rank top users by spend next to their request counts (for example one agent at 1,840 requests versus another at 986).
- Bring Your Own Key — you connect your own OpenAI and Anthropic provider keys, and RelayLM routes through those keys instead of reselling model access.
- Real-time analytics dashboard — a single view reports total cost, request count, active users, and average cost per request, alongside budget usage against a configured limit.
- Model-level cost breakdown — spend is grouped per model, so calls to different models can be compared directly by request volume and cost.
- Daily cost trend — a day-by-day chart shows spend over the last seven days plus the peak day's total.
- Live activity feed — the latest API calls are listed with the user, model, cost, and date of each request.
- Two providers today — OpenAI and Anthropic are supported, with additional providers described as coming soon.
Who should use RelayLM?
- Early-stage startups shipping LLM features: route all OpenAI and Anthropic traffic through one endpoint so a single dashboard shows what the product actually costs to run each day.
- Backend and platform engineers: generate an API key, connect provider keys, and change a few lines of code so requests are tracked without building custom logging.
- Teams running background agents and microservices: attribute spend to named services such as a research agent or retrieval API, and set limits so one runaway job cannot consume the whole budget.
- Founders and engineering leads watching burn: compare spend per model and per user to decide where to downgrade a model or throttle a heavy consumer.
What can you do with RelayLM?
- Running production agents: point an agent service at RelayLM, then compare its spend and request volume against other services to see which one is driving cost.
- Budgeting per team or customer: allocate a budget to a specific user or microservice, then watch the percentage of that limit consumed in the dashboard.
- Model cost comparison: see how much of your bill comes from a high-cost model versus a cheaper one, using the request counts shown next to each model's spend.
- Catching spend spikes early: use the daily cost trend and the live activity feed to spot an unusually expensive day and the calls behind it.
How does RelayLM work?
- Create an API key for your application in the RelayLM dashboard.
- Connect your own OpenAI and Anthropic provider keys through BYOK support.
- Send requests through the RelayLM endpoint, then track usage, tokens, and cost, and set limits to stop unexpected spend.
Alternatives
Other tools in the LLM gateway and observability space include OpenRouter, Helicone, and LiteLLM.
FAQ
Which providers does RelayLM support?
Currently OpenAI and Anthropic, with more providers listed as coming soon. Requests are routed through the provider keys you connect yourself, so model access and billing stay with your existing provider accounts rather than being resold by RelayLM.
Can I use my own API keys?
Yes. RelayLM supports BYOK, so you attach your own OpenAI and Anthropic provider keys in the dashboard and the gateway forwards requests using them. This means provider billing remains on your own accounts while RelayLM adds logging, attribution, and limits on top.
Can I set rate limits or token budgets per user?
Yes. RelayLM lets you enforce usage limits, control spending, and allocate budgets to specific users or microservices. The dashboard shows budget usage as a percentage of a configured limit alongside total cost, request count, and the number of users consuming the budget.
When will RelayLM launch?
RelayLM is in private early access with a waitlist. The stated launch date is 18 August 2026, and the waitlist is aimed at developers and startups building AI applications who want access before general availability.
What does the RelayLM dashboard show?
It reports budget usage against a limit, total cost, total requests, active users, average cost per request, a seven-day cost trend, top users by spend and request count, top models, and a live feed of recent calls with model and cost details.